Services/Managed Services
Managed Services · One operating model

Your roadmap.
Our operations.
One accountable team.

Your team keeps control of the architecture and priorities. YallaCloud runs infrastructure, security, data, resilience, workplace and compliance through one service model and one SLA.
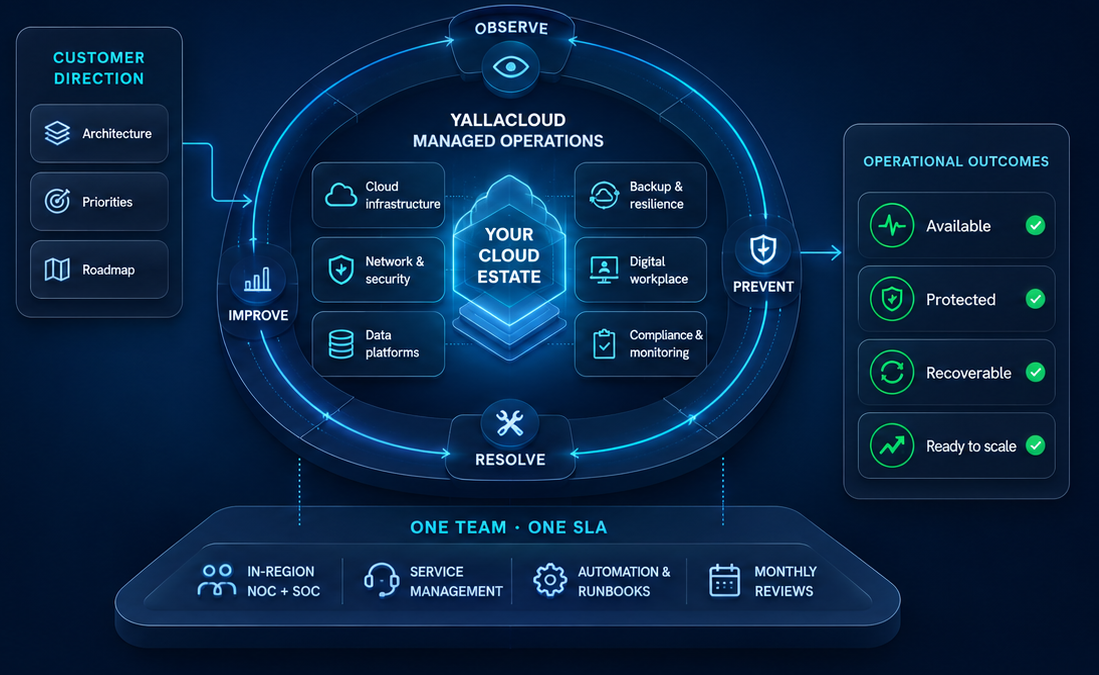
One SLA across domainsNamed service managerRunbooks + automationMonthly service reviews
YallaCloud managed operations running your cloud estate under one SLA
6
Operational domains
24/7/365
In-region NOC + SOC
15 min
P1 first response
99.9%
Availability floor, credit-backed
Moving or modernising first?Migration Services, SAP landscapes and packaged applications run as fixed-scope projects — then land here, operated.
Explore Migrate & Modernise
Under the hood

One operations backbone beneath every domain.

Six domains, one floor — the same runbooks, the same tooling and the same named service manager, so nothing falls between the seams.

Resilience Ops
Cloud Ops
Database Ops
Network Ops
Security Ops
Workspace Ops
One YallaCloud operations backbone
24/7 NOC + SOC
Operations and security on the same floor, in-region — incidents handled once, not passed between vendors.
Runbooks + automation
Every recurring task documented, automated where possible, and reported on. No tribal knowledge.
Named service manager
One person owns your service end to end, with a monthly review against the same SLA.
Credit-backed SLA
Miss the availability floor and the credit lands on your next invoice — no claim form.
SLA & response matrix

Commitments in writing, not intentions.

One SLA covers every managed domain. Severity decides the clock — and the clock is the same whether the incident is in compute, a database or the SOC.

Live platform status →
24/7/365
NOC + SOC coverage, in-region — never follow-the-sun
15 min
P1 first response, any domain, any hour
99.9%
Availability floor on managed services, credit-backed
Monthly
SLA report and service review with your named manager
SeverityWhat qualifiesFirst responseUpdatesTarget to restore
P1 · CriticalProduction down or unusable, or data at risk — a failed failover, a production database offline, an active security incident.15 minEvery 30 min4 hours
P2 · HighMajor degradation with a workaround, or one critical function impaired — replication lagging, a degraded node, WAF in bypass.30 minEvery 2 hours8 hours
P3 · MediumMinor degradation or a non-production issue — a noisy alert, slow non-critical job, dev/test environment fault.4 hoursDaily3 business days
P4 · LowService requests and planned work — access changes, how-to questions, cosmetic issues, scheduled maintenance.8 business hrsOn completionNext change window

Response targets apply 24/7/365 to services under managed operation. Severity is set at triage and can be raised by you at any time — never lowered without your agreement.

Service credits, automatic

Availability is measured per service, per calendar month. Miss the floor and the credit lands on your next invoice — no claim form.

Monthly availabilityCredit
Below 99.9%10%
Below 99.0%25%
Below 95.0%50%

Credit as a percentage of that service's monthly fee. Full terms in theService Level Agreement.

Escalation ladder

Every P1 climbs this ladder on a timer — it never waits on someone noticing.

T+0Duty engineer (L1/L2)Acknowledges, triages severity, opens the incident bridge.
T+30 minDomain lead (L3)Takes over unresolved P1s — compute, network, database or security specialist.
T+60 minIncident manager + your service managerOwns comms, coordinates domains, keeps the 30-minute update cadence.
T+4 hrsYallaCloud leadership + your account executiveExecutive bridge for any P1 still open past its restore target.

Performance against this matrix is reported monthly in theTrust Centrereview pack.

Hand over the pager, keep the control.

A 20-minute conversation about what your team should stop doing manually.

Book a call